python-postgresql build table import csv
As everyone knows, excel can only store one million pieces of data, and csv files can only display one million pieces of data. . . It is unavoidable to use a database. Among the open source databases I know, postgresql has a big feature, which is its high degree of support for geographic data. It is inevitable to use python to operate, that. . .
'''
pm2.5-database
'''
import psycopg2
conn=psycopg2.connect(database="postgres",user="postgres",password="1234",host="127.0.0.1",port="5432")
cur = conn.cursor()
cur.execute("CREATE TABLE mxndata1(data timestamp,point varchar,long double precision,lat double precision,pm25 double precision,\
     pm10 double precision,so2 double precision,no2 double precision,co double precision,\

     o3 double precision,qy double precision,wd double precision,xdsd double precision,fs double precision,fx double precision);")
conn.commit()
cur.close()
conn.close()
'''
postgres=# create table mxndata1
postgres-# (data timestamp,point varchar,long double precision,lat double precision,pm25 double precision,pm10 double precision,so2 double precision,no2 double precision,co double precision,o3 double precision,qy double precision,wd double precision,xdsd double precision,fs double precision,fx double precision);
'''
import psycopg2
from sqlalchemy import create_engine
import pandas as pd
from io import StringIO
data=pd.read_csv(r'D:/minxinan/wrw/2018/2018.csv',header=None,encoding='gbk')
data1 = pd.DataFrame(data)
output = StringIO()
data1.to_csv(output, sep='\t', index=False, header=False)
output1 = output.getvalue()
conn=psycopg2.connect(database="postgres",user="postgres",password="1234",host="127.0.0.1",port="5432")
cur = conn.cursor()
cur.execute("CREATE TABLE mxndata1();")
cur.copy_from(StringIO(output1), 'mxndata1',columns=('data','point','long','lat','pm25','pm10','so2','no2','co','o3','qy','wd','xdsd','fs','fx'))
cur.copy_expert("""COPY mxndata1 FROM 'D:/minxinan/wrw/2018/2018.csv' WITH (FORMAT CSV)""", StringIO(output1))
conn.commit()
cur.close()
conn.close()
print('done')
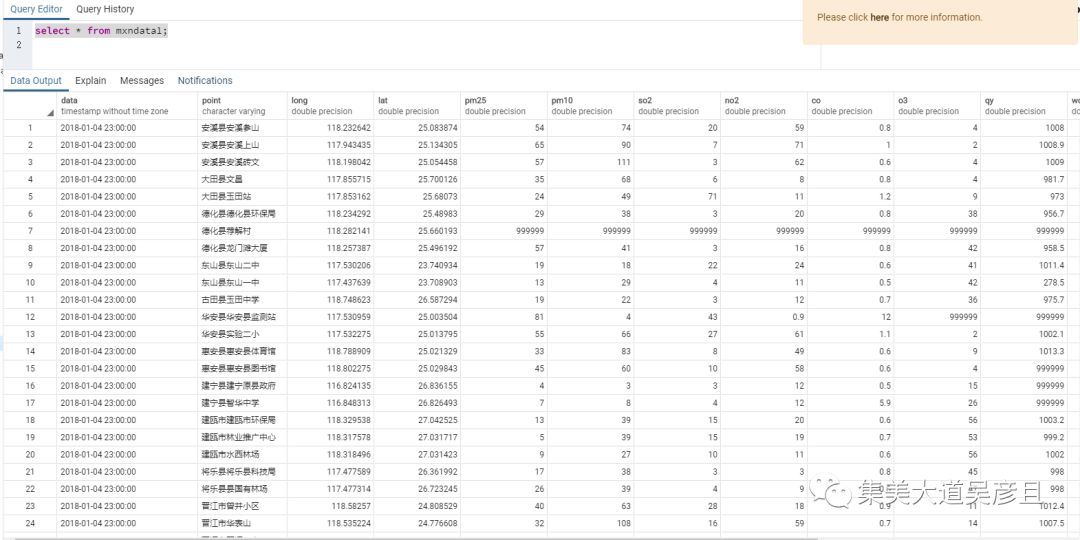
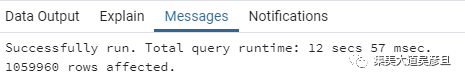
It took more than 10 seconds to open and copy, which is pretty fast
Recommended Posts